

[Apr 05, 2024] ADA-C01 Exam Dumps, ADA-C01 Practice Test Questions
Free ADA-C01 Study Guides Exam Questions and Answer
Snowflake ADA-C01 Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
| Topic 6 |
|
NEW QUESTION # 25
What is required for stages, without credentials, to limit data exfiltration after a storage integration and associated stages are created?
- A. ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = true;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = true;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = false; - B. ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = false;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = false;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = false; - C. ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = false;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = false;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = true; - D. ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = true;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION FOR STAGE_OPERATION = true;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = true;
Answer: D
Explanation:
According to the Snowflake documentation1, stages without credentials are a way to create external stages that use storage integrations to access data files in cloud storage without providing any credentials to Snowflake. Storage integrations are objects that define a trust relationship between Snowflake and a cloud provider, allowing Snowflake to authenticate and authorize access to the cloud storage. To limit data exfiltration after a storage integration and associated stages are created, the following account-level parameters can be set:
* REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION: This parameter enforces that all external stages must be created using a storage integration. This prevents users from creating external stages with inline credentials or URLs that point to unauthorized locations.
* REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION: This parameter enforces that all operations on external stages, such as PUT, GET, COPY, and LIST, must use a storage integration. This prevents users from performing operations on external stages with inline credentials or URLs that point to unauthorized locations.
* PREVENT_UNLOAD_TO_INLINE_URL: This parameter prevents users from unloading data from Snowflake tables to inline URLs that do not use a storage integration. This prevents users from exporting data to unauthorized locations.
Therefore, the correct answer is option D, which sets all these parameters to true. Option A is incorrect because it sets PREVENT_UNLOAD_TO_INLINE_URL to false, which allows users to unload data to inline URLs that do not use a storage integration. Option B is incorrect because it sets both REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION and REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION to false, which allows users to create and operate on external stages without using a storage integration. Option C is incorrect because it sets all the parameters to false, which does not enforce any restrictions on data exfiltration.
NEW QUESTION # 26
For Snowflake network policies, what will occur when the account_level and user_level network policies are both defined?
- A. The account_level policy will override the user_level policy.
- B. A network policy error will be generated with no definitions provided.
- C. The user_level network policies will not be supported.
- D. The user_level policy will override the account_level policy.
Answer: D
Explanation:
Explanation
According to the Network Policies documentation, a network policy can be applied to an account, a security integration, or a user. If there are network policies applied to more than one of these, the most specific network policy overrides more general network policies. The following summarizes the order of precedence:
*Account: Network policies applied to an account are the most general network policies. They are overridden by network policies applied to a security integration or user.
*Security Integration: Network policies applied to a security integration override network policies applied to the account, but are overridden by a network policy applied to a user.
*User: Network policies applied to a user are the most specific network policies. They override both accounts and security integrations.
Therefore, if both the account_level and user_level network policies are defined, the user_level policy will take effect and the account_level policy will be ignored. The other options are incorrect because:
*The account_level policy will not override the user_level policy, as explained above.
*The user_level network policies will be supported, as they are part of the network policyfeature.
*A network policy error will not be generated, as there is no conflict between the account_level and user_level network policies.
NEW QUESTION # 27
A Snowflake Administrator needs to set up Time Travel for a presentation area that includes facts and dimensions tables, and receives a lot of meaningless and erroneous loT dat a. Time Travel is being used as a component of the company's data quality process in which the ingestion pipeline should revert to a known quality data state if any anomalies are detected in the latest load. Data from the past 30 days may have to be retrieved because of latencies in the data acquisition process.
According to best practices, how should these requirements be met? (Select TWO).
- A. Only TRANSIENT tables should be used to ensure referential integrity between the fact and dimension tables.
- B. The DATA_RETENTION_TIME_IN_DAYS should be kept at the account level and never used for lower level containers (databases and schemas).
- C. The fact and dimension tables should have the same DATA_RETENTION_TIME_IN_ DAYS.
- D. The fact and dimension tables should be cloned together using the same Time Travel options to reduce potential referential integrity issues with the restored data.
- E. Related data should not be placed together in the same schema. Facts and dimension tables should each have their own schemas.
Answer: C,D
Explanation:
According to the Understanding & Using Time Travel documentation, Time Travel is a feature that allows you to query, clone, and restore historical data in tables, schemas, and databases for up to 90 days. To meet the requirements of the scenario, the following best practices should be followed:
* The fact and dimension tables should have the same DATA_RETENTION_TIME_IN_DAYS. This parameter specifies the number of days for which the historical data is preserved and can be accessed by Time Travel. To ensure that the fact and dimension tables can be reverted to a consistent state in case of any anomalies in the latest load, they should have the same retention period. Otherwise, some tables may lose their historical data before others, resulting in data inconsistency and quality issues.
* The fact and dimension tables should be cloned together using the same Time Travel options to reduce potential referential integrity issues with the restored data. Cloning is a way of creating a copy of an object (table, schema, or database) at a specific point in time using Time Travel. To ensure that the fact and dimension tables are cloned with the same data set, they should be cloned together using the same AT or BEFORE clause. This will avoid any referential integrity issues that may arise from cloning tables at different points in time.
The other options are incorrect because:
* Related data should not be placed together in the same schema. Facts and dimension tables should each have their own schemas. This is not a best practice for Time Travel, as it does not affect the ability to query, clone, or restore historical data. However, it may be a good practice for data modeling and organization, depending on the use case and design principles.
* The DATA_RETENTION_TIME_IN_DAYS should be kept at the account level and never used for lower level containers (databases and schemas). This is not a best practice for Time Travel, as it limits the flexibility and granularity of setting the retention period for different objects. The retention period can be set at the account, database, schema, or table level, and the most specific setting overrides the more general ones. This allows for customizing the retention period based on the data needs and characteristics of each object.
* Only TRANSIENT tables should be used to ensure referential integrity between the fact and dimension tables. This is not a best practice for Time Travel, as it does not affect the referential integrity between the tables. Transient tables are tables that do not have a Fail-safe period, which means that they cannot be recovered by Snowflake after the retention period ends. However, they still support Time Travel within the retention period, and can be queried, cloned, and restored like permanent tables. The choice of table type depends on the data durability and availability requirements, not on the referential integrity.
NEW QUESTION # 28
A company has set up a new Snowflake account. An Identity Provider (IdP) has been configured for both Single Sign-On (SSO) and SCIM provisioning.
What maintenance is required to ensure that the SCIM provisioning process continues to operate without errors?
- A. The IdP service account requires a new RSA key pair to be generated every six months.
- B. The Administrator must issue a POST RENEW call to the REST API at least once every six months.
- C. The OAuth Bearer Tokens have a lifespan of six months and must be regenerated prior to expiration.
- D. The IdP Administrator must issue a REFRESH transaction at least once every six months to synchronize all users and roles.
Answer: C
Explanation:
According to the Snowflake documentation1, the authentication process for SCIM provisioning uses an OAuth Bearer token and this token is valid for six months. Customers must keep track of their authentication token and can generate a new token on demand. If the token expires, the SCIM provisioning process will fail. Therefore, the token must be regenerated before it expires. The other options are not required for SCIM provisioning.
NEW QUESTION # 29
A Snowflake organization MYORG consists of two Snowflake accounts: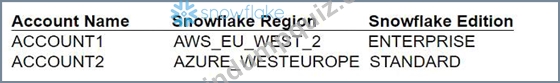
The ACCOUNT1 has a database PROD_DB and the ORGADMIN role enabled.
Management wants to have the PROD_DB database replicated to ACCOUNT2.
Are there any necessary configuration steps in ACCOUNT1 before the database replication can be configured and initiated in ACCOUNT2?
- A. USE ROLE ORGADMIN;
SELECT SYSTEMSGLOBAL ACCOUNT SET_PARAMETER ( 'MYORG. ACCOUNT1',
'ENABLE_ACCOUNT_DATABASE_REPLICATION', 'TRUE');
USE ROLE ACCOUNTADMIN;
ALTER DATABASE PROD_DB ENABLE REPLICATION TO ACCOUNTS MYORG. ACCOUNT2
IGNORE EDITION CHECK; - B. It is not possible to replicate a database from an Enterprise edition Snowflake account to a Standard edition Snowflake account.
- C. No configuration steps are necessary in ACCOUNT1. Replicating databases across accounts within the same Snowflake organization is enabled by default.
- D. USE ROLE ORGADMIN;
SELECT SYSTEMSGLOBAL_ACCOUNT_SET_PARAMETER ('MYORG. ACCOUNT1',
'ENABLE_ACCOUNT_DATABASE_REPLICATION', 'TRUE');
SELECT SYSTEMSGLOBAL_ACCOUNT_SET_PARAMETER ('MYORG. ACCOUNT2',
'ENABLE_ACCOUNT_DATABASE_REPLICATION', 'TRUE');
USE ROLE ACCOUNTADMIN;
ALTER DATABASE PROD DB ENABLE REPLICATION TO ACCOUNTS MYORG. ACCOUNT2;
Answer: A
Explanation:
Explanation
According to the Snowflake documentation1, database replication across accounts within the same organization requires the following steps:
*Link the accounts in the organization using the ORGADMIN role.
*Enable account database replication for both the source and target accounts using the SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER function.
*Promote a local database to serve as the primary database and enable replication to the target accounts using the ALTER DATABASE ... ENABLE REPLICATION TO ACCOUNTS command.
*Create a secondary database in the target account using the CREATE DATABASE ... FROM SHARE command.
*Refresh the secondary database periodically using the ALTER DATABASE ... REFRESH command.
Option A is incorrect because it does not include the step of creating a secondary database in the target account. Option C is incorrect because replicating databases across accounts within the same organization is not enabled by default, but requires enabling account database replication for both the source and target accounts. Option D is incorrect because it is possible to replicate a database from an Enterprise edition Snowflake account to a Standard edition Snowflake account, as long as the IGNORE EDITION CHECK option is used in the ALTER DATABASE ... ENABLE REPLICATION TO ACCOUNTS command2.
Option B is correct because it includes all the necessary configuration steps in ACCOUNT1, except for creating a secondary database in ACCOUNT2, which can be done after the replication is enabled.
NEW QUESTION # 30
A data provider wants to share data from multiple databases with a data consumer account.
How can this be accomplished?
- A. The data provider needs to create a secure view and grant the REFERENCE_USAGE privilege on each database referenced by the secure view.
- B. The data provider needs to create a secure view and must grant the REFERENCE_USAGE privilege on the database where the secure view is created.
- C. The data provider needs to create a secure view and grant the REFERENCE_USAGE privilege to a database role to include objects from multiple databases in a share
- D. The data provider needs to create a secure view and grant the USAGE privilege on each database referenced by the secure view.
Answer: A
Explanation:
Explanation
Option B is the correct answer because it follows the steps described in the Snowflake documentation for sharing data from multiple databases using secure views. The data provider needs to grant the REFERENCE_USAGE privilege on each database that contains objects referenced by the secure view, and the USAGE privilege only on the database where the secure view is created. Option A is incorrect because it grants the USAGE privilege instead of the REFERENCE_USAGE privilege. Option C is incorrect because it grants the REFERENCE_USAGE privilege to a database role, which is not supported. Option D is incorrect because it grants the REFERENCE_USAGE privilege on the wrong database.
NEW QUESTION # 31
A user has enrolled in Multi-factor Authentication (MFA) for connecting to Snowflake. The user informs the Snowflake Administrator that they lost their mobile phone the previous evening.
Which step should the Administrator take to allow the user to log in to the system, without revoking their MFA enrollment?
- A. Alter the user and set DISABLE_MFA to true, which will suspend the MFA requirement for 24 hours.
- B. Alter the user and set MINS TO BYPASS MFA to a value that will disable MFA long enough for the user to log in.
- C. Instruct the user to connect to Snowflake using SnowSQL, which does not support MFA authentication.
- D. Instruct the user to append the normal URL with /?mode=mfa_bypass&code= to log on.
Answer: B
Explanation:
The MINS_TO_BYPASS_MFA property allows the account administrator to temporarily disable MFA for a user who has lost their phone or changed their phone number1. The user can log in without MFA for the specified number of minutes, and then re-enroll in MFA using their new phone1. This does not revoke their MFA enrollment, unlike the DISABLE_MFA property, which cancels their enrollment and requires them to re-enroll from scratch1. The other options are not valid ways to bypass MFA, as SnowSQL does support MFA authentication2, and there is no such URL parameter as /?mode=mfa_bypass&code= for Snowflake3
NEW QUESTION # 32
A Snowflake user runs a complex SQL query on a dedicated virtual warehouse that reads a large amount of data from micro-partitions. The same user wants to run another query that uses the same data set.
Which action would provide optimal performance for the second SQL query?
- A. Assign additional clusters to the virtual warehouse.
- B. Use the RESULT_SCAN function to post-process the output of the first query.
- C. Increase the STATEMENT_TIMEOUT_IN_SECONDS parameter in the session.
- D. Prevent the virtual warehouse from suspending between the running of the first and second queries.
Answer: B
Explanation:
According to the Using Persisted Query Results documentation, the RESULT_SCAN function allows you to query the result set of a previous command as if it were a table. This can improve the performance of the second query by avoiding reading the same data from micro-partitions again. The other actions do not provide optimal performance for the second query because:
* Assigning additional clusters to the virtual warehouse does not affect the data access speed, but only the query execution speed. It also increases the cost of the warehouse.
* Increasing the STATEMENT_TIMEOUT_IN_SECONDS parameter in the session does not improve the performance of the query, but only allows it to run longer before timing out. It also increases the risk of resource contention and deadlock.
* Preventing the virtual warehouse from suspending between the running of the first and second queries does not guarantee that the data will be cached in memory, as Snowflake uses a least recently used (LRU) cache eviction policy. It also increases the cost of the warehouse.
https://docs.snowflake.com/en/user-guide/querying-persisted-results
NEW QUESTION # 33
If the query matches the definition, will Snowflake always dynamically rewrite the query to use a materialized view?
- A. Yes, because materialized views are always faster.
- B. No, because joins are not supported by materialized views.
- C. No, because the materialized view may not be up-to-date.
- D. No, because the optimizer might decide against it.
Answer: D
Explanation:
Snowflake's query optimizer can automatically rewrite queries against the base table or regular views to use the materialized view instead, if the query matches the definition of the materialized view1. However, this is not always guaranteed, as the optimizer might decide against using the materialized view based on various factors, such as the freshness of the data, the size of the result set, the complexity of the query, and the availability of the materialized view2. Therefore, the answer is no, because the optimizer might decide against it.
NEW QUESTION # 34
An Administrator receives data from a Snowflake partner. The partner is sharing a dataset that contains multiple secure views. The Administrator would like to configure the data so that only certain roles can see certain secure views.
How can this be accomplished?
- A. Apply RBAC directly onto the partner's shared secure views.
- B. Clone the data and insert it into a company-owned share and apply the desired RBAC on the new tables.
- C. Create views over the incoming shared database and apply the desired RBAC onto these views.
- D. Individually grant imported privileges onto the schema in the share.
Answer: C
Explanation:
Explanation
According to the Snowflake documentation1, secure views are only exposed to authorized users who have been granted the role that owns the view. Therefore, applying RBAC directly onto the partner's shared secure views (option A) is not possible, as the administrator does not own those views. Individually granting imported privileges onto the schema in the share (option B) is also not feasible, as the privileges granted on the schema do not apply to existing secure views, only tofuture ones2. Cloning the data and inserting it into a company-owned share (option C) is not recommended, as it would create unnecessary duplication of data and increase storage costs. The best option is to create views over the incoming shared database and apply the desired RBAC onto these views (option D). This way, the administrator can control the access to the data based on the roles in their account, without modifying the original data or views from the partner.
NEW QUESTION # 35
When adding secure views to a share in Snowflake, which function is needed to authorize users from another account to access rows in a base table?
- A. CURRENT ACCOUNT
- B. CURRENT_USER
- C. CURRENT_CLIENT
- D. CURRENT_ROLE
Answer: B
Explanation:
According to the Working with Secure Views documentation, secure views are designed to limit access to sensitive data that should not be exposed to all users of the underlying table(s). When sharing secure views with another account, the view definition must include a function that returns the identity of the user who is querying the view, such as CURRENT_USER, CURRENT_ROLE, or CURRENT_ACCOUNT. These functions can be used to filter the rows in the base table based on the user's identity. For example, a secure view can use the CURRENT_USER function to compare the user name with a column in the base table that contains the authorized user names. Only the rows that match the user name will be returned by the view. The CURRENT_CLIENT function is not suitable for this purpose, because it returns the IP address of the client that is connected to Snowflake, which is not related to the user's identity.
NEW QUESTION # 36
A company's Snowflake account has multiple roles. Each role should have access only to data that resides in the given role's specific region.
When creating a row access policy, which code snippet below will provide privileges to the role ALL_ACCESS_ROLE to see all rows regardless of region, while the other roles can only see rows for their own regions?
- A. create or replace row access policy region policy as (region_value varchar) returns boolean ->
'ALL ACCESS_ROLE' = current_role ()
and exists (
select 1 from entitlement_table
where role = current_role ()
and region = region_value
) - B. create or replace row access policy region policy as (region_value varchar) returns boolean ->
'ALL_ACCESS_ROLE' = current_role ()
or exists (
select 1 from entitlement_table
where role = current_role ()
and region = region_value
) - C. create or replace row access policy region policy as (region_value varchar) returns boolean ->
'ALL ACCESS ROLE' = current_role ()
) - D. create or replace row access policy region policy as (region_value varchar) returns boolean -> exists ( select 1 from entitlement_table where role = current_role () and region = region_value )
Answer: B
Explanation:
Explanation
This code snippet will create a row access policy that returns true if the current role is ALL_ACCESS_ROLE or if the current role matches the region value in the entitlement_table. This means that the ALL_ACCESS_ROLE can see all rows regardless of region, while the other roles can only see rows for their own regions. According to the Snowflake documentation, the CURRENT_ROLE context function returns the name of the current role for the session. The EXISTS function returns true if the subquery returns any rows.
The OR operator returns true if either operand is true. Therefore, this code snippet satisfies the requirements of the question.
NEW QUESTION # 37
What are benefits of using Snowflake organizations? (Select TWO).
- A. Administrators can change Snowflake account editions on-demand based on need.
- B. User administration is simplified across all accounts within the organization.
- C. Administrators can simplify data movement across all accounts within the organization.
- D. Administrators have the ability to create accounts in any available cloud provider or region.
- E. Administrators can monitor and understand usage across all accounts in the organization.
Answer: D,E
Explanation:
Explanation
According to the Snowflake documentation1, organizations are a feature that allows linking the accounts owned by a business entity, simplifying account management and billing, replication and failover, data sharing, and other account administration tasks. Some of the benefits of using organizations are:
*Administrators can monitor and understand usage across all accounts in the organization using the ORGANIZATION_USAGE schema, which provides historical usage data for all accounts in the organization via views in a shared database named SNOWFLAKE2. This can help to optimize costs and performance across the organization.
*Administrators have the ability to create accounts in any available cloud provider or region using the CREATE ACCOUNT command, which allows specifying the cloud platform and region for the new account3.
This can help to meet the business needs and compliance requirements of the organization.
Option A is incorrect because administrators cannot change Snowflake account editions on-demand based on need, but rather have to contact Snowflake Support to request an edition change4. Option C is incorrect because administrators cannot simplify data movement across all accounts within the organization, but rather have to enable account database replication for both the source and target accounts, and use the ALTER DATABASE ... ENABLE REPLICATION TO ACCOUNTS command to promote a local database to serve as the primary database and enable replication to the target accounts5. Option D is incorrect because user administration is not simplified across all accounts within the organization, but rather requires creating and managing users, roles, and privileges for each account separately, unless using a federated authentication method such as SSO or SCIM.
NEW QUESTION # 38
Which commands can be performed by a user with the ORGADMIN role but not the ACCOUNTADMIN role? (Select TWO).
- A. SHOW ORGANIZATION ACCOUNTS;
- B. GRANT ROLE ORGADMIN TO USER <username>;
- C. SHOW REGIONS;
- D. SHOW USERS;
- E. SELECT SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER (
'ACCOUNT LOCATOR',
'ENABLE ACCOUNT DATABASE_REPLICATION',
'true'
);
Answer: A,E
Explanation:
Explanation
According to the Snowflake documentation1, the ORGADMIN role is a special system role that is responsible for managing operations at the organization level, such as creating and viewing accounts, enabling database replication, and setting global account parameters. The ACCOUNTADMIN role is a system role that is responsible for managing operations at the account level, such as creating and managing users, roles, warehouses, databases, and shares. Therefore, the commands that can be performed by the ORGADMIN role but not the ACCOUNTADMIN role are:
*SHOW ORGANIZATION ACCOUNTS: This command lists all the accounts in the organization and their properties, such as region, edition, and status2. The ACCOUNTADMIN role can only show the current account and its properties using the SHOW ACCOUNTS command3.
*SELECT SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER: This function sets a global account parameter for an account in the organization, such as enabling account database replication4. The ACCOUNTADMIN role can only set local account parameters using the ALTER ACCOUNT command.
Option A is incorrect because the SHOW REGIONS command can be executed by any role, not just the ORGADMIN role. Option B is incorrect because the SHOW USERS command can be executed by the ACCOUNTADMIN role, as well as any role that has been granted the MONITOR privilege on the account.
Option D is incorrect because the GRANT ROLE ORGADMIN TO USER <username> command can be executed by the ACCOUNTADMIN role, as well as any role that has been granted the ORGADMIN role1.
NEW QUESTION # 39
An organization's sales team leverages this Snowflake query a few times a day:
SELECT CUSTOMER ID, CUSTOMER_NAME, ADDRESS, PHONE NO
FROM CUSTOMERS
WHERE LAST UPDATED BETWEEN TO_DATE (CURRENT_TIMESTAMP) AND (TO_DATE (CURRENT_TIMESTAMP) -7); What can the Snowflake Administrator do to optimize the use of persisted query results whenever possible?
- A. Leverage the CURRENT_DATE function for date calculations.
- B. Assign everyone on the sales team to the same security role.
- C. Wrap the query in a User-Defined Function (UDF) to match syntax execution.
- D. Assign everyone on the sales team to the same virtual warehouse.
Answer: A
Explanation:
According to the web search results from my predefined tool search_web, one of the factors that affects the reuse of persisted query results is the exact match of the query syntax1. If the query contains functions that return different values for successive runs, such as CURRENT_TIMESTAMP, then the query will not match the previous query and will not benefit from the cache. To avoid this, the query should use functions that return consistent values for the same day, such as CURRENT_DATE, which returns the current date without the time component2. Option A is incorrect because wrapping the query in a UDF does not guarantee the syntax match, as the UDF may also contain dynamic functions. Option B is incorrect because the virtual warehouse does not affect the persisted query results, which are stored at the account level1. Option C is incorrect because the security role does not affect the persisted query results, as long as the role has the necessary privileges to access the tables and views used in the query1.
1: Using Persisted Query Results | Snowflake Documentation 2: Date and Time Functions | Snowflake Documentation
NEW QUESTION # 40
In which scenario will use of an external table simplify a data pipeline?
- A. When accessing a Snowflake table that references data files located in cloud storage
- B. When accessing a Snowflake table from a relational database
- C. When accessing a Snowflake table from an external database within the same region
- D. When continuously writing data from a Snowflake table to external storage
Answer: A
Explanation:
Explanation
According to the Introduction to External Tables documentation, an external table is a Snowflake feature that allows you to query data stored in an external stage as if the data were inside a table in Snowflake. The external stage is not part of Snowflake, so Snowflake does not store or manage the stage. This simplifies the data pipeline by eliminating the need to load the data into Snowflake before querying it. External tables can access data stored in any format that the COPY INTO <table> command supports, such as CSV, JSON, AVRO, ORC, or PARQUET. The other scenarios do not involve external tables, but rather require data loading, unloading, or federation.
NEW QUESTION # 41
A user with the proper role issues the following commands when setting up and activating network policies:
CREATE OR REPLACE NETWORK POLICY foo_policy
ALLOWED_IP_LIST = ( '1.1.1.0/24', '2.2.2.0/24' , '3.3. 3. 0/24' )
BLOCKED IP LIST = ( '1.1.1.1')
COMMENT = 'Account level policy';
ALTER ACCOUNT SET NETWORK_POLICY=FOO_POLICY;
CREATE OR REPLACE NETWORK POLICY bar_policy
ALLOWED_IP_LIST = ('3.3.3.0/24')
BLOCKED IP LIST = ('3.3.3.10')
COMMENT = 'user level policy';
ALTER USER userl SET NETWORK_POLICY=BAR_POLICY;
Afterwards, user1 attempts to log in to Snowflake from IP address 3.3.3.10.
Will the login be successful?
- A. No, because 3.3.3.10 is found in the BLOCKED_IP_LIST of bar_policy.
- B. No, because 3.3.3.10 is not found in the ALLOWED_IP_LIST of foo_policy.
- C. Yes, because 3.3.3.10 is found in the ALLOWED_IP_LIST of foo_policy.
- D. Yes, because 3.3.3.10 is found in the ALLOWED_IP_LIST of bar_policy.
Answer: A
Explanation:
According to the Snowflake documentation1, network policies are a feature that allows restricting access to your account based on user IP address. A network policy can be applied to an account, a user, or a security integration, and can specify a list of allowed IP addresses and a list of blocked IP addresses. If there are network policies applied to more than one of these, the most specific network policy overrides more general network policies. In this case, the user1 has a network policy (bar_policy) applied to them, which overrides the account-level network policy (foo_policy). The bar_policy allows access only from the IP range 3.3.3.0/24, and blocks access from the IP address 3.3.3.10. Therefore, the user1 will not be able to log in to Snowflake from IP address 3.3.3.10, as it is found in the BLOCKED_IP_LIST of bar_policy. Option A is incorrect because the ALLOWED_IP_LIST of bar_policy does not override the BLOCKED_IP_LIST of bar_policy. Option C is incorrect because the ALLOWED_IP_LIST of foo_policy does not apply to user1, as it is overridden by the user-level network policy. Option D is incorrect because the ALLOWED_IP_LIST of foo_policy does not matter, as it is overridden by the user-level network policy.
NEW QUESTION # 42
An Administrator has a user who needs to be able to suspend and resume a task based on the current virtual warehouse load, but this user should not be able to modify the task or start a new run.
What privileges should be granted to the user to meet these requirements? (Select TWO).
- A. OPERATE on the task
- B. OWNERSHIP on the task
- C. USAGE on the database and schema containing the task
- D. OWNERSHIP on the database and schema containing the task
- E. EXECUTE TASK on the task
Answer: A,C
NEW QUESTION # 43
The ACCOUNTADMIN of Account 123 works with Snowflake Support to set up a Data Exchange. After the exchange is populated with listings from other Snowflake accounts, what roles in Account 123 are allowed to request and get data?
- A. Any role with USAGE privilege on the Data Exchange
- B. Any role with IMPORT SHARE and CREATE DATABASE privileges
- C. Any role that the listing provider has designated as authorized
- D. Only the ACCOUNTADMIN role, and no other roles
Answer: A
Explanation:
To request and get data from a Data Exchange, the role in Account 123 must have the USAGE privilege on the Data Exchange object. This privilege allows the role to view the listings and request access to the data. According to the Snowflake documentation, "To view the listings in a data exchange, a role must have the USAGE privilege on the data exchange object. To request access to a listing, a role must have the USAGE privilege on the data exchange object and the IMPORT SHARE privilege on the account." The other options are either incorrect or not sufficient to request and get data from a Data Exchange. Option A is incorrect, as the ACCOUNTADMIN role is not the only role that can request and get data, as long as other roles have the necessary privileges. Option C is incorrect, as the IMPORT SHARE and CREATE DATABASE privileges are not required to request and get data, but only to create a database from a share after the access is granted. Option D is incorrect, as the listing provider does not designate the authorized roles in Account 123, but only approves or denies the requests from Account 123.
NEW QUESTION # 44
A Snowflake Administrator is investigating why a query is not re-using the persisted result cache.
The Administrator found the two relevant queries from the SNOWFLAKE. ACCOUNT_USAGE.
QUERY_HISTORY view:
Why is the second query re-scanning micro-partitions instead of using the first query's persisted result cache?
- A. The second query includes a CURRENT_DATE () function.
- B. The queries are executed with two different roles.
- C. The queries are executed with two different virtual warehouses.
- D. The second query includes a CURRENT_TIMESTAMP () function.
Answer: C
Explanation:
Explanation
The inclusion of the CURRENT_TIMESTAMP() function in the second query prevents it from re-using the first query's persisted result cache because this function makes each execution unique due to the constantly changing timestamp. According to the Snowflake documentation, "The query does not include non-reusable functions, which return different results for successive runs of the same query. UUID_STRING, RANDOM, and RANDSTR are good examples of non-reusable functions." The CURRENT_TIMESTAMP() function is another example of a non-reusable function, as it returns the current date and time at the start of query execution, which varies for each run. Therefore, the second query is not identical to the first query, and the result cache is not reused. The other options are either incorrect or irrelevant to the question. Option B is incorrect, as the CURRENT_DATE() function is a reusable function, as it returns the same value for all queries executed within the same day. Option C is irrelevant, as the virtual warehouse used to execute the query does not affect the result cache reuse. Option D is also irrelevant, as the role used to execute the query does not affect the result cache reuse, as long as the role has the necessary access privileges for all the tables used in the query.
NEW QUESTION # 45
A retailer uses a TRANSACTIONS table (100M rows, 1.2 TB) that has been clustered by the STORE_ID column (varchar(50)). The vast majority of analyses on this table are grouped by STORE_ID to look at store performance.
There are 1000 stores operated by the retailer but most sales come from only 20 stores. The Administrator notes that most queries are currently experiencing poor pruning, with large amounts of bytes processed by even simple queries.
Why is this occurring?
- A. The cardinality of the stores to transaction count ratio is too low to use the STORE_ID as a clustering key.
- B. The STORE_ID should be numeric.
- C. The table is not big enough to take advantage of the clustering key.
- D. Sales across stores are not uniformly distributed.
Answer: D
Explanation:
Explanation
According to the Snowflake documentation1, clustering keys are most effective when the data is evenly distributed across the key values. If the data is skewed, such as in this case where most sales come from only
20 stores out of 1000, then the micro-partitions will not be well-clustered and the pruning will be poor. This means that more bytes will be scanned by queries, even if they filter by STORE_ID. Option A is incorrect because the data type of the clustering key does not affect the pruning. Option B is incorrect because the table is large enough to benefit from clustering, if the data was more balanced. Option D is incorrect because the cardinality of the clustering key is not relevant for pruning, as long as the key values are distinct.
1: Considerations for Choosing Clustering for a Table | Snowflake Documentation
NEW QUESTION # 46
......
ADA-C01 Exam Dumps, ADA-C01 Practice Test Questions: https://skillsoft.braindumpquiz.com/ADA-C01-exam-material.html